Skip to content
Inspire AI Lab

← All case studies

Series · 12 parts

eMunshi Engineering Series

A technical series on the data foundation Inspire AI Lab built for eMunshi, a legal research and practice platform for Indian advocates: recovering text from tens of millions of court documents in multiple scripts, establishing case identity, verifying links between documents and cases, generating headnotes that cannot invent content, and maintaining a verified statute library. Each part records what was measured, what went wrong, and what was learned.

Six court-document tiles in legacy-font ASCII, Gujarati, English and Hindi lead through four steps, recover, identify, verify and extract, above the line "What was measured, what went wrong, and what was learned."

12 partspublishes Thursdaysfirst part 1 of 12 live

Next up Part 2: Pre-Unicode Legacy Fonts: Recovering Indic Text Encoded as ASCII ·

Data foundation Parts 1–9

Recovering text from court documents in multiple scripts, establishing case identity, verifying links between documents and cases, headnotes that cannot invent content, and a verified statute library.

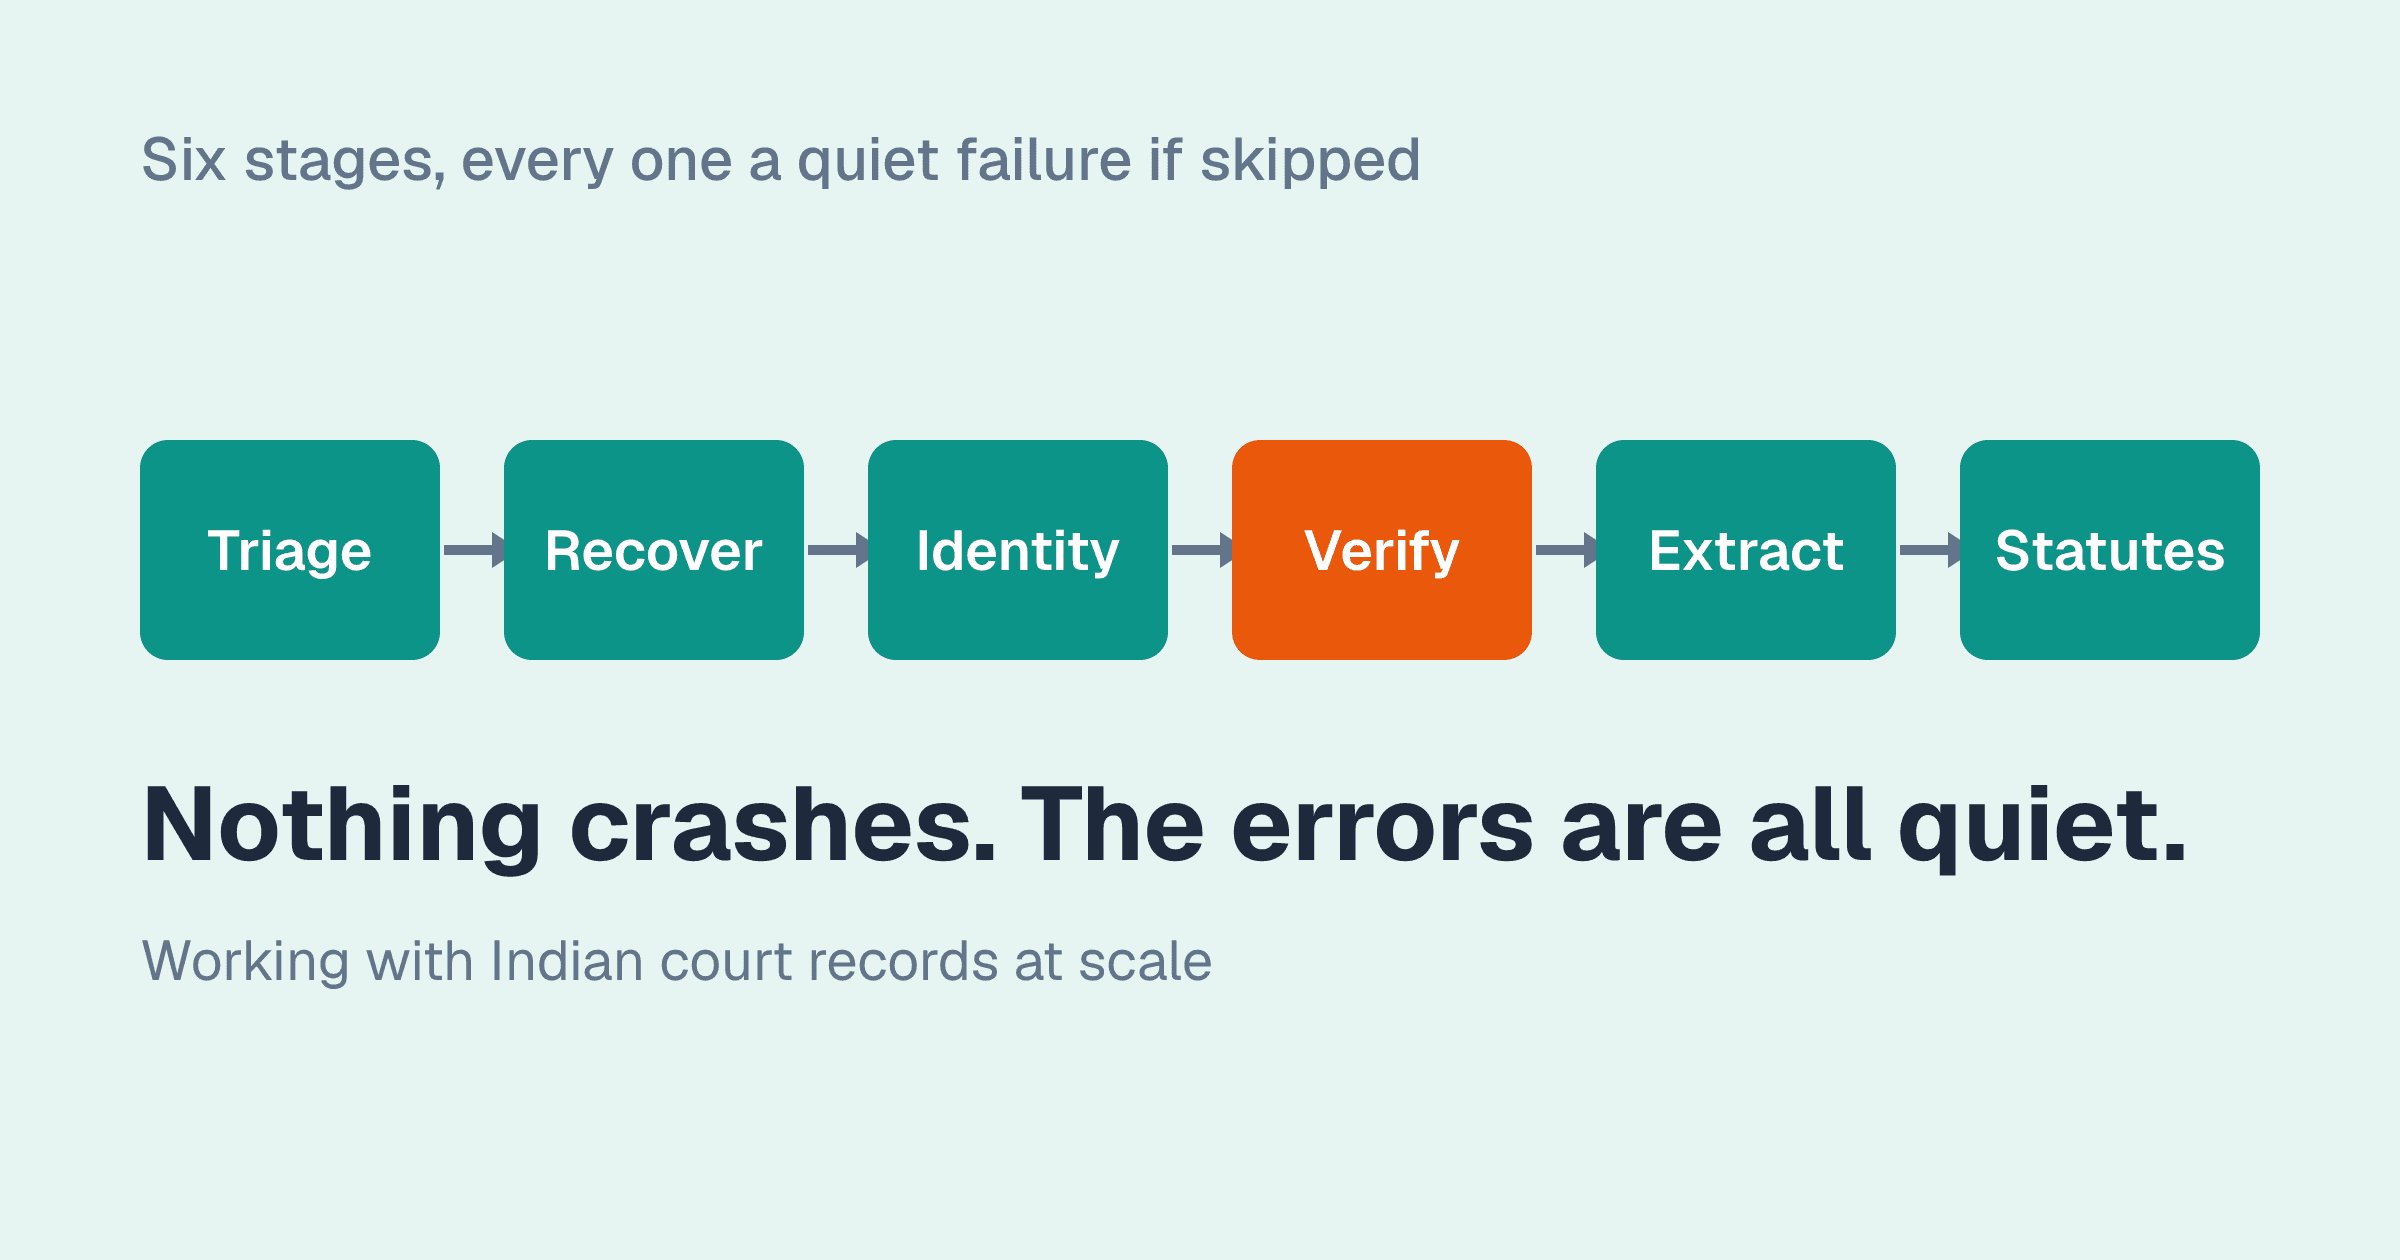
  1. Six pipeline stages in a row (Triage, Recover, Identity, Verify, Extract, Statutes) with Verify highlighted, above the line: Nothing crashes. The errors are all quiet.
    Part 1

    Working with Indian Court Records at Scale

    This series describes how we engineered the data foundation of eMunshi, a legal research and practice platform for Indian advocates, working with tens of millions of court documents. This first article explains why Indian court records are hard to work with, how the pipeline is organized, and the principles that run through every part that follows.

  2. Part 2Coming

    Pre-Unicode Legacy Fonts: Recovering Indic Text Encoded as ASCII

  3. Part 3Coming

    OCR as Verification, Not Default

  4. Part 4Coming

    Headnotes That Cannot Invent Content

  5. Part 5Coming

    Party Extraction Across Inconsistent Formats

  6. Part 6Coming

    A Verified Statute Library

  7. Part 7Coming

    Case Identity: Why a Printed Case Number Is Not an Identifier

  8. Part 8Coming

    Imperfect Source Data: Misfiled Documents, Missing Metadata, and Relinking

  9. Part 9Coming

    Operating AI Coding Agents on a Large Document Pipeline

Product capabilities Parts 10–12

Citation verification, party identity in due diligence, and court-rules-aware drafting on the legal research and practice platform.

  1. Part 10Coming

    Citation Existence Verification

  2. Part 11Coming

    Resolving Party Identity in Due Diligence

  3. Part 12Coming

    Court-Rules-Aware Drafting