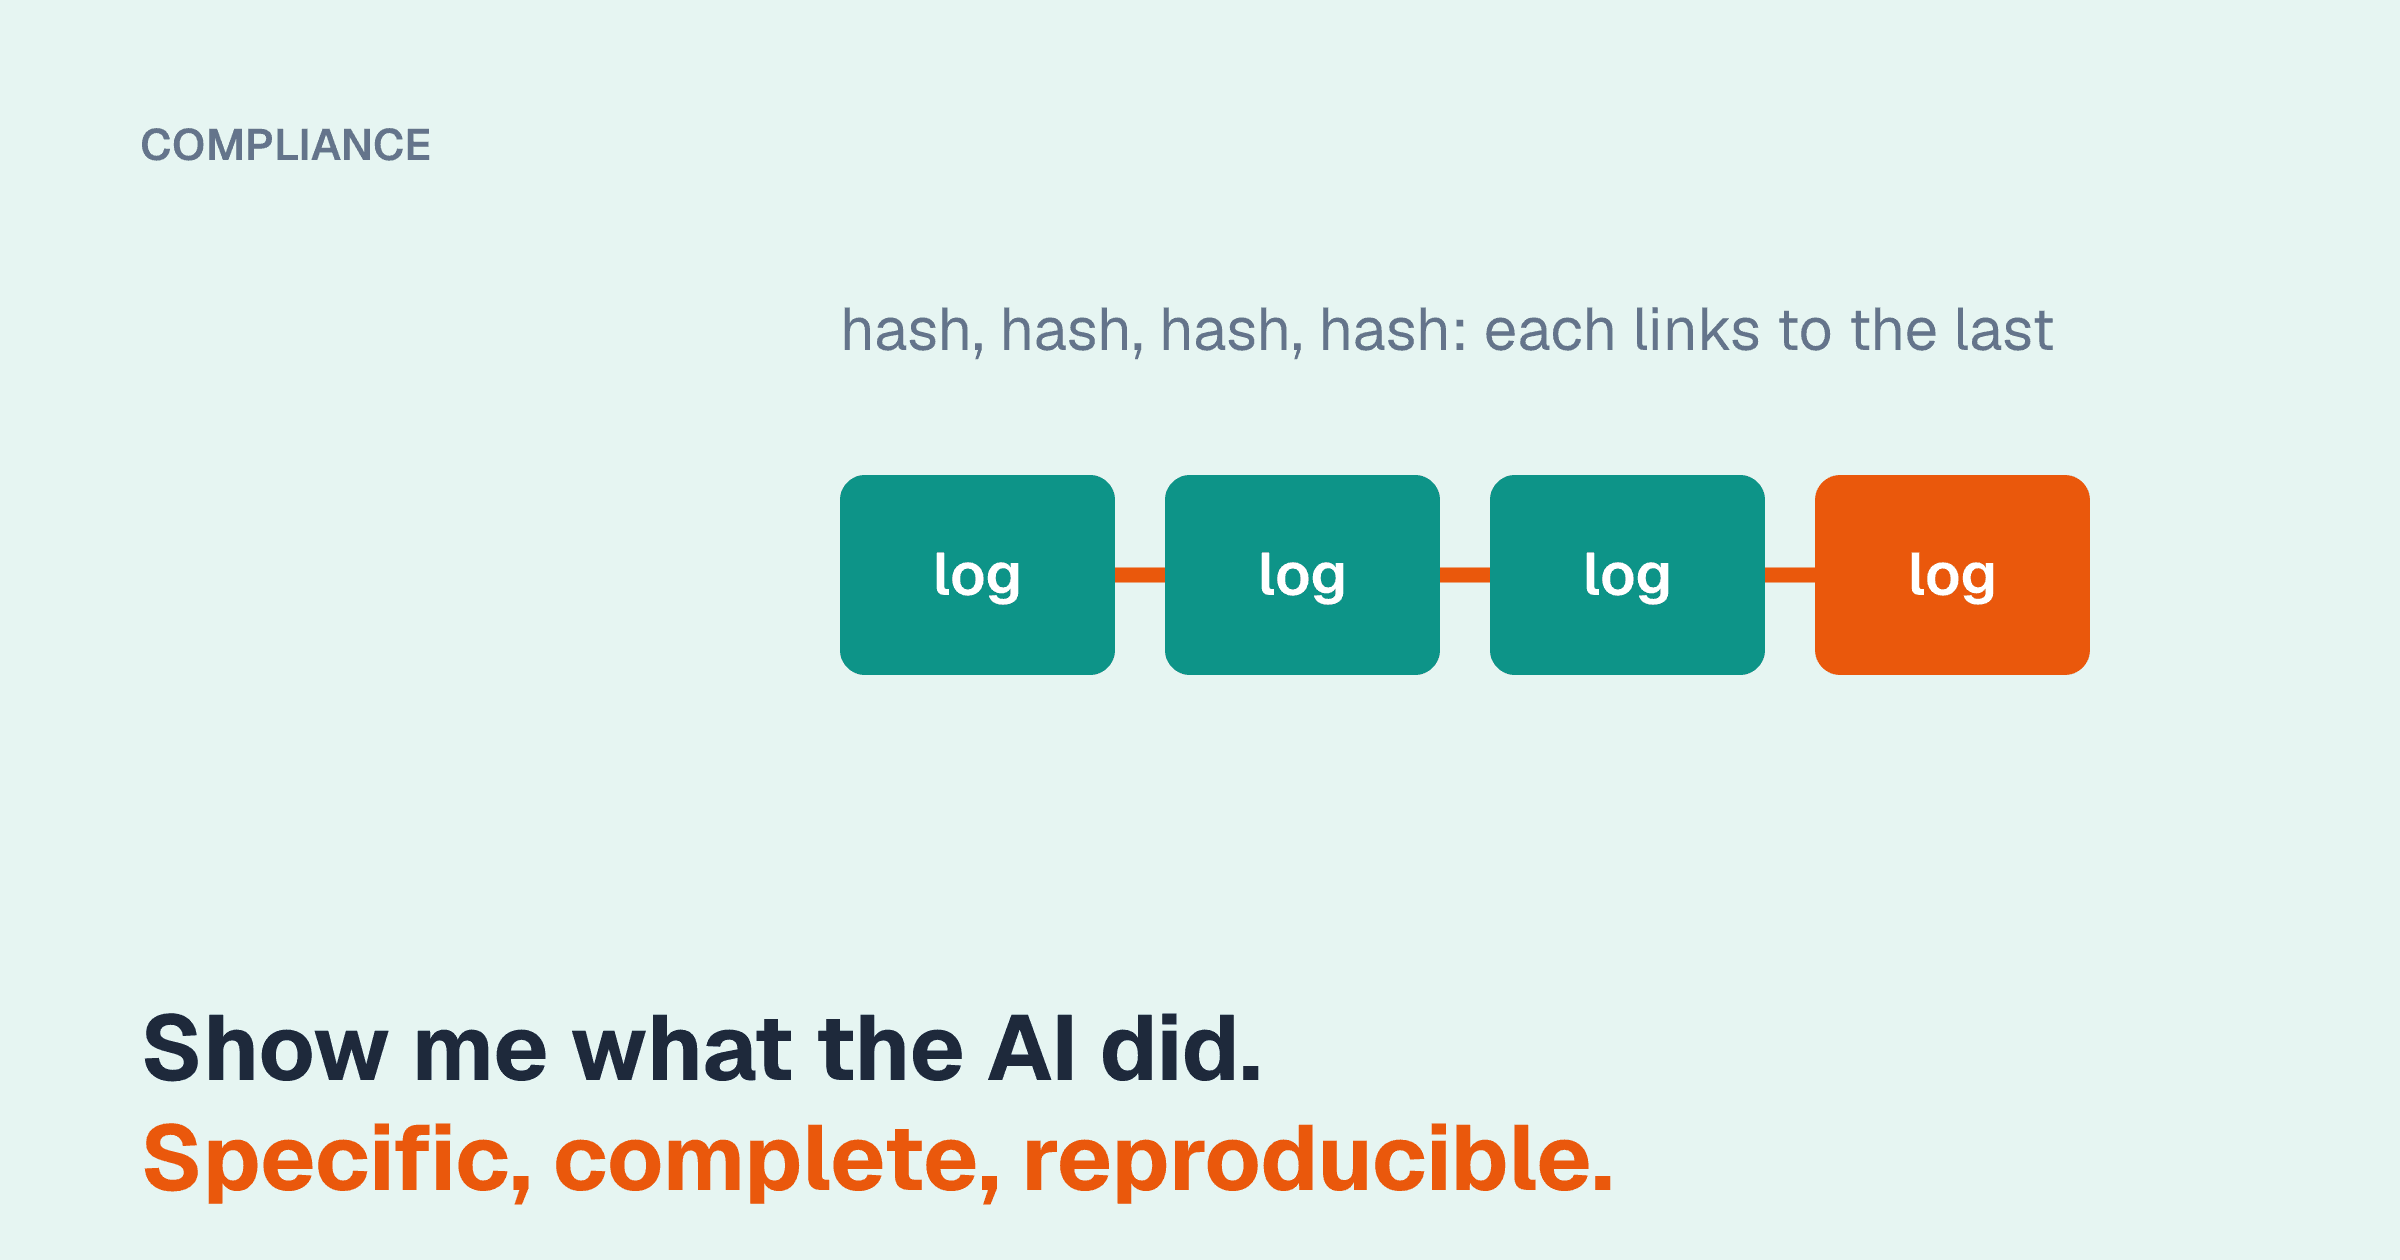
The most common compliance failure on LLM deployments we audit is incomplete logging. Teams log enough to debug their application but not enough to satisfy an examiner asking "what did the AI tell this customer six months ago, and why?"
The gap between debug-grade logging and audit-grade logging is wider than most teams realize. This is the architecture we recommend for systems that need to clear an audit.
What an auditor actually asks
A few questions we've seen on real audits and examinations:
- "Show me every AI-generated customer communication for [account X] between [dates]."
- "For [specific communication], reproduce what the AI saw and what it produced."
- "What model version was running at the time?"
- "Who reviewed and approved this communication, and what changes were made?"
- "How were the AI's outputs validated against [policy]?"
- "Show me the training data used to fine-tune the model."
- "If we asked the model the same question today, would it give the same answer? Why not?"
These questions have three properties:
- Specific — they target a particular interaction or customer, not aggregate statistics.
- Reconstructive — they want to recreate what happened, not just describe it.
- Complete — they expect every relevant artifact to be retrievable.
A production system that logs aggregate token counts and a few request samples can't answer them.
The architecture
A complete LLM audit trail captures, per request:
Request identifiers
- Unique request ID
- Session / conversation ID (if multi-turn)
- Customer / account ID (with appropriate access controls)
- User / employee who initiated the request (if not the customer)
- Timestamp at request start
Model identifiers
- Model name (e.g., "qwen-2.5-72b-instruct")
- Model version (specific commit hash or release tag)
- Quantization level (e.g., "Q4_K_M-custom-2026-03-12")
- Adapter version (LoRA hash if applicable)
- Serving infrastructure (which physical host)
Request content
- Full prompt as sent to the model (system prompt + retrieved context + user input)
- Retrieved context with source identifiers (which documents, which chunks, ranking scores)
- Sampling parameters (temperature, top-k, top-p, max tokens, seed)
Response content
- Full model output
- Token-level log probabilities (for some use cases — typically off by default for cost)
- Streaming chunk timing (if applicable)
Downstream consumption
- Was the output used? Modified? Discarded?
- Who reviewed it, when, what they changed
- What customer-facing communication (if any) resulted
Performance metrics
- Latency (TTFT, total)
- Token counts (input, output)
- Cost (per request, with attribution)
That's a lot of fields. The right shape is a structured event per request, indexed for retrieval by any of the identifier fields.
Storage and retention
Two storage tiers:
Hot tier for recent records (typically 30-90 days). Available for quick retrieval, supporting customer service questions, immediate audit responses, and routine analysis. Often Postgres, BigQuery, or similar.
Cold tier for retention. WORM-compliant if required by industry (financial services 17a-4, healthcare HIPAA, legal-side bar requirements). Glacier, Azure Archive Storage, or on-prem write-once-read-many systems. Retention period set by industry regulation.
A common mistake: log everything to a single tier and run out of budget. The data shapes are different — hot needs query performance, cold needs durability and immutability. Different storage for different lifetimes.
Reproducibility
The hardest auditor question is "would the model give the same answer today?"
For weights-pinned deployments (on-prem with a specific GGUF), the answer is "yes, deterministically, if we replay the same inputs with the same sampling seed." This requires:
- Pinned model artifacts (the exact bytes of the weights file at the time of the request)
- Pinned tokenizer (rare to change but worth versioning)
- Pinned inference engine version (vLLM 0.6.x vs 0.7.x can produce slightly different outputs)
- Pinned sampling parameters (already in the request record)
- Seeded sampling (if temperature > 0, you need the seed)
With these, you can take any historical request from the audit log, replay it on the current infrastructure, and confirm that the response would be reproduced. This is the gold standard.
For API-based deployments, reproducibility is harder. OpenAI's "gpt-4o" today is not the same weights as six months ago — they update models on a schedule the customer doesn't control. Reproducing a historical response is generally not possible.
This is why audit-sensitive deployments tend toward on-prem.
Versioning the model lifecycle
A model in production has a lifecycle: base model + custom calibration + LoRA adapter + serving stack. Each component is versioned; each version is associated with a date range of deployment.
Audit records reference the model version; the model version registry knows what files those versions correspond to.
deployment_id      | start_date    | end_date      | components
---------------------------------------------------------------
prod-v2026-03-12   | 2026-03-12   | 2026-04-08    | base:llama-3.3-70b-instruct@internal-v7,
                   |              |               | quant:q4_k_m-custom-spider-2026-03-08,
                   |              |               | adapter:lora-contracts-2026-02-15,
                   |              |               | engine:vllm-0.7.3
prod-v2026-04-08   | 2026-04-08   | (current)     | (refreshed adapter)
                   |              |               | adapter:lora-contracts-2026-04-05
A request from 2026-03-20 was processed by prod-v2026-03-12, which used a specific adapter that may have been retired. The model file registry retains the retired artifacts so reproducibility is possible years later.
Bias and outcome monitoring
For regulated deployments (especially financial services, employment, healthcare), audits look at outcomes, not just records. Did the AI treat customers fairly? Did approval rates differ by demographic?
This requires:
- Outcome metrics tracked per population segment (demographic, geographic, account tier, etc.)
- Periodic statistical review for divergences
- Documented response when divergences are found
The technical work is straightforward — log enough demographic context to slice by. The harder work is the governance: who reviews the slices, what thresholds trigger action, how findings are documented.
What about privacy
Comprehensive audit logging conflicts with data minimization principles. Tension:
- Audit wants every prompt and response indefinitely
- Privacy wants minimum data, deletion on schedule
Resolution:
- Per-request encryption with field-level keys
- Tiered retention based on data sensitivity
- Cryptographic deletion when retention periods expire (delete the key, the encrypted data is unrecoverable)
- Documented justification for what's retained, why, and for how long
We've shipped this architecture on deployments under GDPR, HIPAA, and various state privacy laws. The pattern works; it adds engineering complexity.
The honest minimum
Not every deployment needs full audit architecture. The minimum we recommend for any production deployment:
- Request-level logging with unique IDs (not aggregate stats)
- Model version metadata per request
- Retention sufficient for the regulatory regime (industry-specific)
- Documented retention schedule
- Documented purge process
Add the more elaborate pieces when the regulatory posture demands them.
The deployments that get into trouble are the ones with debug-grade logging and a quarterly aggregate dashboard. When the auditor arrives, the answer to "show me what the AI did for this specific customer" is some variation of "we can't easily retrieve that." That's the failure that costs.
Build the audit trail before you need it. Retrofitting under audit pressure is much more expensive than designing it in.